Audit reasoning with :TOUCHED edges
|
Available on NAMS: No. The procedure on this page needs the Bolt backend. With the hosted NAMS backend its operations are unavailable: depending on the call, the client raises |
This procedure requires Bolt. The Python NAMS client accepts
touched_entities on record_tool_call but silently drops it, so no
:TOUCHED edges are written and no error is raised. Its reasoning store has no
on_tool_call_recorded hook (AttributeError). Both clients expose
client.query.cypher, but that does not establish that the hosted graph
contains these nodes or relationships.
|
How to make every agent reasoning step queryable from any entity it referenced through a direct step-to-entity relationship.
When you supply triggered_by_message_id to start_trace and message_id to
record_tool_call, the library can link
(ReasoningTrace)-[:INITIATED_BY]→(Message)-[:MENTIONS]→(Entity) and
(ToolCall)-[:TRIGGERED_BY]→(Message), when the corresponding message and entity links exist. Those links are
optional; recording a trace alone does not create them. The library also provides a direct
(:ReasoningStep)-[:TOUCHED]→(:Entity) edge that you can write either
explicitly or via an observer hook. This page shows both.
Prerequisites
Use a dedicated AuraDB instance from the first memory tutorial’s Aura setup, with exported NEO4J_URI, NEO4J_USERNAME, and NEO4J_PASSWORD. Set OPENAI_API_KEY for the selected embedding provider. Prepare the example files below and install the provider extra:
Create a local folder and virtual environment for the examples on this page. The commands reuse an existing environment without changing its files:
mkdir -p ~/agent-memory-tutorials
cd ~/agent-memory-tutorials
if [ -e .venv ]; then
  printf '%s\n' 'Using the existing virtual environment.'
else
  python3 -m venv .venv
fi
source .venv/bin/activate
Expected: ~/agent-memory-tutorials is your working directory and its virtual environment is active. Install the published SDK with the command below.
Each complete code block labelled Save as names a file to create in this folder using your editor. Copy the entire block, including imports and the entry point. Expand each helper disclosure and use Copy code to copy its full source. Keep all files together so their imports resolve.
When continuing from another tutorial or guide, retain the existing environment, configuration, session files, and .tutorial-state/. Reuse unchanged helper files; compare an existing file before replacing it, and finish any pending cleanup or recovery before changing the code that owns its state.
python -m pip install 'neo4j-agent-memory[openai]==0.7.0'The maintained program core_memory_recipes.py imports core_memory_settings.py from the same directory. That helper explicitly selects Bolt and disables automatic extraction/enrichment. Each command creates a new ID suffix so it can run independently. Embedding requests send example text to OpenAI.
Save the three complete files below in agent-memory-tutorials/. If a file already exists from another guide, keep its matching contents; do not replace configuration or state files. The task-specific excerpt in the next section explains the operation to run.
Open the helper below and save its complete source as aura_connection.py in ~/agent-memory-tutorials.
Show aura_connection.py
aura_connection.py"""Read the Aura connection exported by the documentation setup commands."""
import os
class AuraConfigurationError(ValueError):
"""Missing or invalid tutorial settings, with no credential values in errors."""
def aura_config():
required = ("NEO4J_URI", "NEO4J_USERNAME", "NEO4J_PASSWORD")
missing = [name for name in required if not os.environ.get(name, "").strip()]
if missing:
raise AuraConfigurationError("Export the Aura connection settings: " + ", ".join(missing))
uri = os.environ["NEO4J_URI"]
if not uri.startswith("neo4j+s://"):
raise AuraConfigurationError("NEO4J_URI must use the Aura neo4j+s:// connection scheme")
database = os.environ.get("NEO4J_DATABASE", "neo4j")
if not database.strip():
raise AuraConfigurationError("NEO4J_DATABASE must not be empty")
return {
"uri": uri,
"username": os.environ["NEO4J_USERNAME"],
"password": os.environ["NEO4J_PASSWORD"],
"database": database,
}Complete core_memory_settings.py
core_memory_settings.py"""Shared settings for the three Aura-backed memory tutorials."""
from aura_connection import aura_config
from neo4j_agent_memory import MemorySettings
def settings():
return MemorySettings(
backend="bolt",
neo4j=aura_config(),
embedding="openai/text-embedding-3-small",
llm=None,
extraction={"extractor_type": "none"},
resolution={"strategy": "none"},
geocoding={"enabled": False},
enrichment={"enabled": False},
)Complete core_memory_recipes.py
core_memory_recipes.py"""Independent Bolt how-to recipes; each command creates a distinct test dataset."""
import argparse
import asyncio
from datetime import datetime, timedelta, timezone
from uuid import uuid4
from core_memory_settings import settings
from neo4j_agent_memory import MemoryClient
from neo4j_agent_memory.core.memory import ToolCallStatus
from neo4j_agent_memory.memory.long_term import DeduplicationConfig, LongTermMemory
from neo4j_agent_memory.schema.models import EntityRef, TraceOutcome
# tag::messages[]
async def messages(client, run_id):
session = f"docs-messages-{run_id}"
# Explicit timestamps record when each turn happened; untimed rows are stamped in list order.
start = datetime.now(timezone.utc)
stored = await client.short_term.add_messages_batch(
session,
[
{
"role": "user",
"content": "Please find wide walking shoes.",
"metadata": {"topic": "shopping"},
"timestamp": start.isoformat(),
},
{
"role": "assistant",
"content": "I will look for wide fits.",
"timestamp": (start + timedelta(seconds=1)).isoformat(),
},
],
user_identifier=f"docs-user-{run_id}",
extract_entities=False,
)
conversation = await client.short_term.get_conversation(session)
assert [m.id for m in conversation.messages] == [m.id for m in stored]
summary = await client.short_term.get_conversation_summary(
session,
include_entities=False,
summarizer=lambda _transcript: "A shopper requested wide walking shoes.",
)
assert summary.message_count == 2
print(summary.summary)
# This semantic search is database-wide; it is not used for user-scoped readback.
matches = await client.short_term.search_messages("wide walking shoes", threshold=0.0, limit=5)
for message in matches:
print(message.content, message.metadata.get("similarity"))
print(f"Verified: ordered message IDs and summary count; session={session}")
# end::messages[]
# tag::entities[]
async def entities(client, run_id):
person, _ = await client.long_term.add_entity(
f"Maya {run_id}",
"PERSON",
aliases=[f"M. {run_id}"],
description="An engineer at the fictional Northstar laboratory.",
attributes={"team": "robotics"},
resolve=False,
deduplicate=False,
)
company, _ = await client.long_term.add_entity(
f"Northstar {run_id}", "ORGANIZATION", resolve=False, deduplicate=False
)
edge = await client.long_term.add_relationship(person, company, "WORKS_AT", confidence=1.0)
fact = await client.long_term.add_fact(person.name, "works_at", company.name)
assert fact.as_triple == (person.name, "works_at", company.name)
rows = await client.query.cypher(
"MATCH (a:Entity {id: $source})-[r:RELATED_TO {id: $edge}]->(b:Entity) "
"RETURN a.name AS source, r.type AS relation, b.name AS target",
{"source": str(person.id), "edge": str(edge.id)},
)
assert rows == [{"source": person.name, "relation": "WORKS_AT", "target": company.name}]
facts = await client.long_term.get_facts_about(person.name)
assert any(item.as_triple == fact.as_triple for item in facts)
print(f"Verified: entity relationship and fact readback; person={person.id}")
# end::entities[]
# tag::preferences[]
async def preferences(client, run_id):
user = f"docs-preference-user-{run_id}"
product, _ = await client.long_term.add_entity(
f"Walking shoes {run_id}",
"OBJECT",
subtype="PRODUCT",
generate_embedding=False,
resolve=False,
deduplicate=False,
)
scope = EntityRef(id=str(product.id))
# Disable embedding-based global preference dedupe for independent user revisions.
old = await client.long_term.add_preference(
"budget",
"Spend at most USD 60",
user_identifier=user,
applies_to=[scope],
generate_embedding=False,
context="Explicit user statement",
)
replacement = await client.long_term.add_preference(
"budget",
"Spend at most USD 80",
user_identifier=user,
applies_to=[scope],
generate_embedding=False,
context="Explicit user revision",
)
await client.long_term.supersede_preference(old.id, replacement.id)
active = await client.long_term.get_preferences_for(user, applies_to=scope)
historical = await client.long_term.get_preferences_for(user, active_only=False)
assert [p.id for p in active] == [replacement.id]
assert {p.id for p in historical} == {old.id, replacement.id}
context = "\n".join(f"{p.category}: {p.preference}" for p in active)
print(context)
print(f"Verified: current preference and retained history; user={user}")
# end::preferences[]
# tag::reasoning[]
async def reasoning(client, run_id):
session = f"docs-trace-{run_id}"
trace = await client.reasoning.start_trace(session, "Check a deliberately unavailable product")
step = await client.reasoning.add_step(trace.id, action="lookup_product")
try:
raise LookupError("The fictional product is unavailable")
except LookupError as error:
await client.reasoning.record_tool_call(
step.id,
"lookup_product",
{"sku": "missing-example-sku"},
status=ToolCallStatus.ERROR,
error=str(error),
duration_ms=0,
)
await client.reasoning.complete_trace(
trace.id,
outcome=TraceOutcome(success=False, summary=str(error), error_kind="no_results"),
)
saved = await client.reasoning.get_trace_with_steps(trace.id)
assert saved is not None and saved.success is False
assert len(saved.steps) == 1 and len(saved.steps[0].tool_calls) == 1
assert saved.steps[0].tool_calls[0].status == ToolCallStatus.ERROR
print(f"Verified: failed tool call and completed failure trace; trace={trace.id}")
# end::reasoning[]
# tag::deduplication[]
async def deduplication(client, run_id):
store = LongTermMemory(
client.graph,
embedder=client.long_term.embedder,
# The same bands MemoryClient applies from ResolutionConfig (0.90 merge, 0.85 review).
deduplication=DeduplicationConfig(
auto_merge_threshold=0.90, flag_threshold=0.85, use_fuzzy_matching=False
),
)
# Create an isolated pair without similarity-based merging so manual review is reproducible.
target, _ = await store.add_entity(
f"Northstar Laboratory {run_id}", "ORGANIZATION", resolve=False, deduplicate=False
)
source, _ = await store.add_entity(
f"Northstar Lab {run_id}", "ORGANIZATION", resolve=False, deduplicate=False
)
# The application has established that this specific pair denotes the same organization.
merged = await store.merge_duplicate_entities(source.id, target.id)
assert merged is not None
rows = await client.query.cypher(
"MATCH (s:Entity {id: $source}), (t:Entity {id: $target}) "
"RETURN s.merged_into AS merged_into, t.aliases AS aliases",
{"source": str(source.id), "target": str(target.id)},
)
assert rows[0]["merged_into"] == str(target.id)
assert source.name in rows[0]["aliases"]
stats = await store.get_deduplication_stats()
print(f"Verified: reviewed pair merged into {target.id}; merged nodes={stats.merged_entities}")
# end::deduplication[]
# tag::audit[]
async def audit(client, run_id):
session = f"docs-audit-{run_id}"
client_name = f"Anthem {run_id}"
consultant_name = f"Sara {run_id}"
trace = await client.reasoning.start_trace(session, "Recommend a consulting team")
step = await client.reasoning.add_step(trace.id, action="recommend_team")
await client.reasoning.record_tool_call(
step.id,
tool_name="recommend_team",
arguments={"client_name": client_name},
result=[{"consultant": consultant_name}],
touched_entities=[
EntityRef(name=client_name, type="CLIENT"),
EntityRef(name=consultant_name, type="PERSON"),
],
)
await client.reasoning.complete_trace(
trace.id,
outcome=TraceOutcome(success=True, summary="Matched one consultant"),
)
rows = await client.query.cypher(
"MATCH (:Entity {name: $client_name})<-[:TOUCHED]-(s:ReasoningStep)"
"<-[:HAS_STEP]-(rt:ReasoningTrace) "
"RETURN rt.task AS task, s.action AS action, rt.outcome AS outcome",
{"client_name": client_name},
)
assert rows == [
{"task": trace.task, "action": "recommend_team", "outcome": "Matched one consultant"}
]
print(f"Verified: touched-entity audit query found the trace; client={client_name}")
# end::audit[]
async def main():
commands = {
"messages": messages,
"entities": entities,
"preferences": preferences,
"reasoning": reasoning,
"deduplication": deduplication,
"audit": audit,
}
parser = argparse.ArgumentParser()
parser.add_argument("command", choices=commands)
args = parser.parse_args()
async with MemoryClient(settings()) as client:
await commands[args.command](client, uuid4().hex[:8])
if __name__ == "__main__":
asyncio.run(main())Run the audit command’s fragment below in the same async function with that client and run_id, exactly as the maintained program does. Existing entity IDs are also accepted when linking to entities already stored by your application. The CLIENT entity type in this example is a domain-specific audit label.
Goal
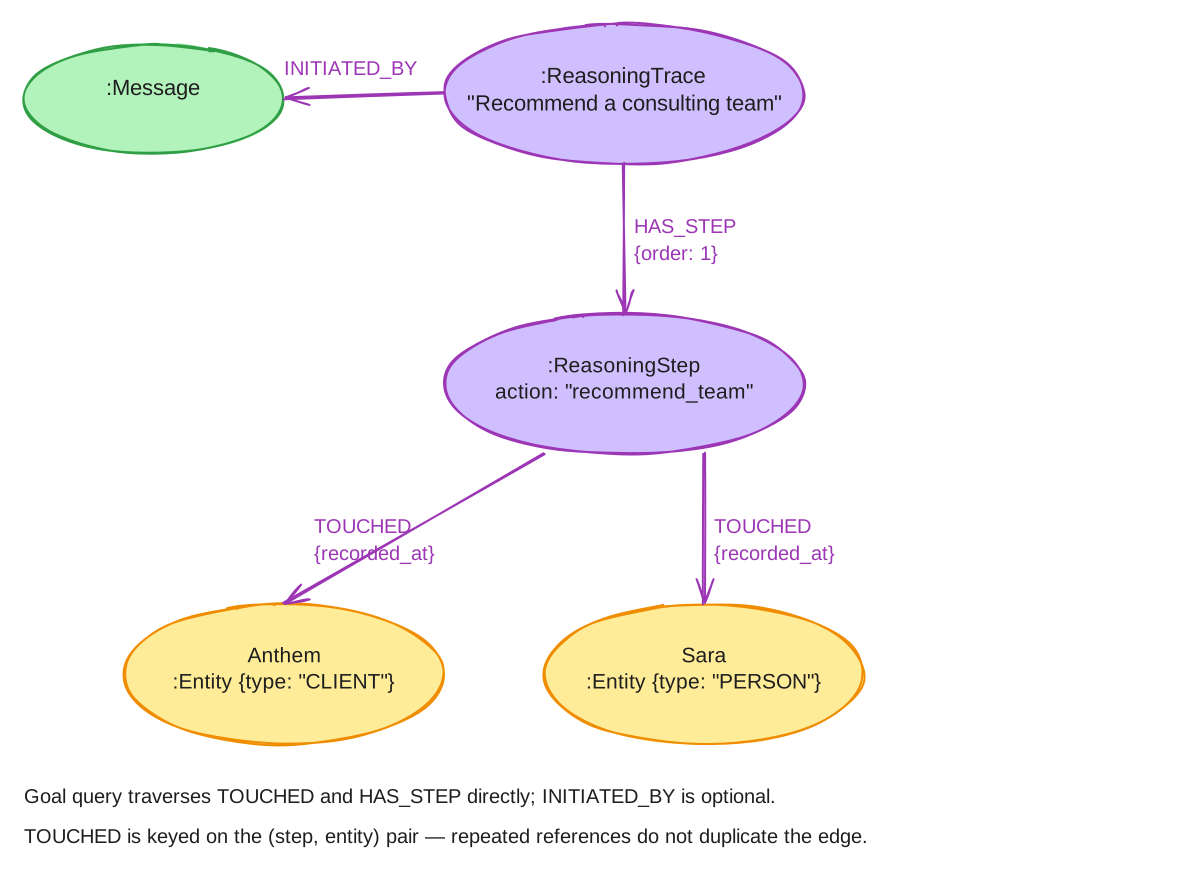
Find traces through a direct ReasoningStep → Entity edge. The query also
traverses HAS_STEP and optionally the initiating message. For the rationale
behind linking reasoning steps directly to entities instead of only through
messages, see Why Neo4j? Graph memory architecture.
MATCH (:Entity {name: 'Anthem'})<-[:TOUCHED]-(s:ReasoningStep)
      <-[:HAS_STEP]-(rt:ReasoningTrace)
OPTIONAL MATCH (rt)-[:INITIATED_BY]->(m:Message)
RETURN rt.task, s.thought, rt.outcome, rt.success, rt.error_kind,
       rt.metrics_json, m.content AS triggered_by
TraceOutcome lands as queryable columns — rt.outcome is the summary
string, with success, error_kind and metrics_json beside it — not an
opaque blob.
1. Choose how to record touched entities
Approach 1 — Pass touched_entities directly
Simplest: when you know the touched entities at call time, pass them
into record_tool_call(…).
from neo4j_agent_memory.schema.models import EntityRef

await client.reasoning.record_tool_call(
    step.id,
    tool_name="recommend_team",
    arguments={"client_name": "Anthem"},
    result=[{"consultant": "Sara"}],
    touched_entities=[
        EntityRef(name="Anthem", type="CLIENT"),
        EntityRef(name="Sara", type="PERSON"),
    ],
)
The library matches an existing entity when id is provided; a missing ID
does not create an entity or an edge. Otherwise it MERGEs by name + type,
or by name when no type is supplied,
and writes a (:ReasoningStep)-[:TOUCHED {recorded_at}→(:Entity)]
edge. The edge is keyed on the (step, entity) pair, so repeated references
do not create duplicate edges. Each record_tool_call still records a new tool call.
Entity types are uppercase strings. The MERGE stores type
verbatim, so type="Client" creates a second :Entity node that
add_entity (which uppercases) would identify differently. Prefer
EntityRef(id=…) when the entity already exists.
|
Approach 2 — Register an observer hook
Often the touched entities aren’t known until the tool result is in
hand (e.g. recommend_team returns a list of consultants). Register a
hook that fires after every record_tool_call and adds edges based on
the result:
from typing import Any

from neo4j_agent_memory.schema.models import EntityRef


def infer_touched(
    tool_name: str,
    arguments: dict[str, Any],
    result: Any,
) -> list[EntityRef]:
    """Domain-specific mapping from tool calls to EntityRef lists."""
    refs: list[EntityRef] = []
    if tool_name == "recommend_team":
        client_name = arguments.get("client_name")
        if client_name:
            refs.append(EntityRef(name=client_name, type="CLIENT"))
        if isinstance(result, list):
            for row in result:
                if isinstance(row, dict) and "consultant" in row:
                    refs.append(EntityRef(name=row["consultant"], type="PERSON"))
    return refs


@client.reasoning.on_tool_call_recorded
async def link_touched_entities(tool_call, ctx):
    for ref in infer_touched(tool_call.tool_name, tool_call.arguments, tool_call.result):
        await ctx.add_touched_edge(ref)
The hook receives a ToolCall and a HookContext (both in
neo4j_agent_memory.memory.reasoning); annotate them when you type-check
your agent — examples/audit-trail/main.py shows the annotated form.
client.reasoning is typed as the portable ReasoningProtocol by
default, which does not carry the bolt-only hook. Annotate client as
MemoryClient[ShortTermMemory, LongTermMemory, ReasoningMemory] — or
cast it — so its reasoning attribute narrows to the concrete
ReasoningMemory class, which is what makes the decorator and
get_tool_stats() type-check.
|
Exceptions raised inside observer hooks are logged and suppressed. Failures
persisting the tool call or its explicit touched_entities can still propagate. Hooks fire in registration order, after the tool
call is persisted and after any touched_entities passed to
record_tool_call have been written.
2. Record a structured outcome
Pair :TOUCHED with TraceOutcome to make audit queries filterable
by structured failure mode:
from neo4j_agent_memory.schema.models import TraceOutcome

await client.reasoning.complete_trace(
    trace.id,
    outcome=TraceOutcome(
        success=False,
        summary="Recommendation failed: no consultants matched skills",
        error_kind="no_results",
        related_entities=[
            EntityRef(name="Anthem", type="CLIENT"),
        ],
        metrics={"tools_called": 1.0},
    ),
)
error_kind is a top-level indexed property on :ReasoningTrace, so
you can scan failure modes cheaply:
MATCH (rt:ReasoningTrace {error_kind: 'timeout'})
RETURN rt.task, rt.completed_at, rt.outcome
ORDER BY rt.completed_at DESC
The related_entities list is materialized as :TOUCHED edges on the
most recent step of the trace, when one exists. Completing a trace with no
steps does not create a :TOUCHED edge.
3. Run and verify
The fragment below matches the maintained program’s audit() function,
which supplies imports, client setup, unique IDs, and asyncio.run around
it. It starts a trace and step in the same recommend_team domain used
throughout this page, records the tool call with touched_entities,
completes the trace, then runs the goal query above and prints the result.
trace = await client.reasoning.start_trace(session, "Recommend a consulting team")
step = await client.reasoning.add_step(trace.id, action="recommend_team")
await client.reasoning.record_tool_call(
    step.id,
    tool_name="recommend_team",
    arguments={"client_name": client_name},
    result=[{"consultant": consultant_name}],
    touched_entities=[
        EntityRef(name=client_name, type="CLIENT"),
        EntityRef(name=consultant_name, type="PERSON"),
    ],
)
await client.reasoning.complete_trace(
    trace.id,
    outcome=TraceOutcome(success=True, summary="Matched one consultant"),
)
rows = await client.query.cypher(
    "MATCH (:Entity {name: $client_name})<-[:TOUCHED]-(s:ReasoningStep)"
    "<-[:HAS_STEP]-(rt:ReasoningTrace) "
    "RETURN rt.task AS task, s.action AS action, rt.outcome AS outcome",
    {"client_name": client_name},
)
assert rows == [
    {"task": trace.task, "action": "recommend_team", "outcome": "Matched one consultant"}
]
print(f"Verified: touched-entity audit query found the trace; client={client_name}")
python core_memory_recipes.py auditExpected: Verified: touched-entity audit query found the trace; client=Anthem ….
Confirm the returned task and outcome belong to this trace and the touched
entity is the intended node. For an existing entity, filter on its ID instead
of name. A missing row can mean a missing step, a missing entity ID, or a
failed hook; inspect application logs and the explicit write results.
The command retains its example records for inspection. Remove the disposable tutorial database using that tutorial’s cleanup command when finished. Do not substitute an unrestricted delete query against an existing database.
Optional: Retrieve similar steps
For case-based imitation prompting, search past steps by their
thought/action — coarser-grained get_similar_traces searches the
trace task, which is often too high-level:
results = await client.reasoning.search_steps(
    "query schema before joining",
    limit=10,
    success_only=True,
)
for r in results:
    print(f"({r.similarity:.2f}) parent={r.parent_task!r} step={r.step.thought!r}")
Each result includes the parent trace’s task and outcome so the LLM can see "in a similar situation, here’s what worked."
See also
-
Record and verify a failed tool call — the underlying trace + step + tool-call API.
-
Audit-trail example — runnable end-to-end example using this how-to.