Designing resilient multi-region cluster deploymentsEnterprise Edition
|
A note on terminology
In this guide, the terms cloud region and data center are used interchangeably to represent distinct, isolated geographical deployment locations. Whether you deploy Neo4j on your own physical hardware or in the cloud, the architectural rules for latency, quorum, and replication remain identical. |
Overview
To maximize cluster resilience, you have to choose between two strategies:
-
Stretching a single cluster across multiple data centers.
-
Or deploying multiple independent clusters with the database replication between them - officially released in Neo4j 2026.08.
Before choosing a multi-region cluster architecture, you have to consider the following:
-
Recovery point objective (RPO).
-
Recovery time objective (RTO).
-
Database write performance/workload.
-
Network cost.
Deploying multiple independent clustersIntroduced in 2026.08
Multiple independent clusters provide regional isolation by running Neo4j clusters in different locations and replicating databases between them.
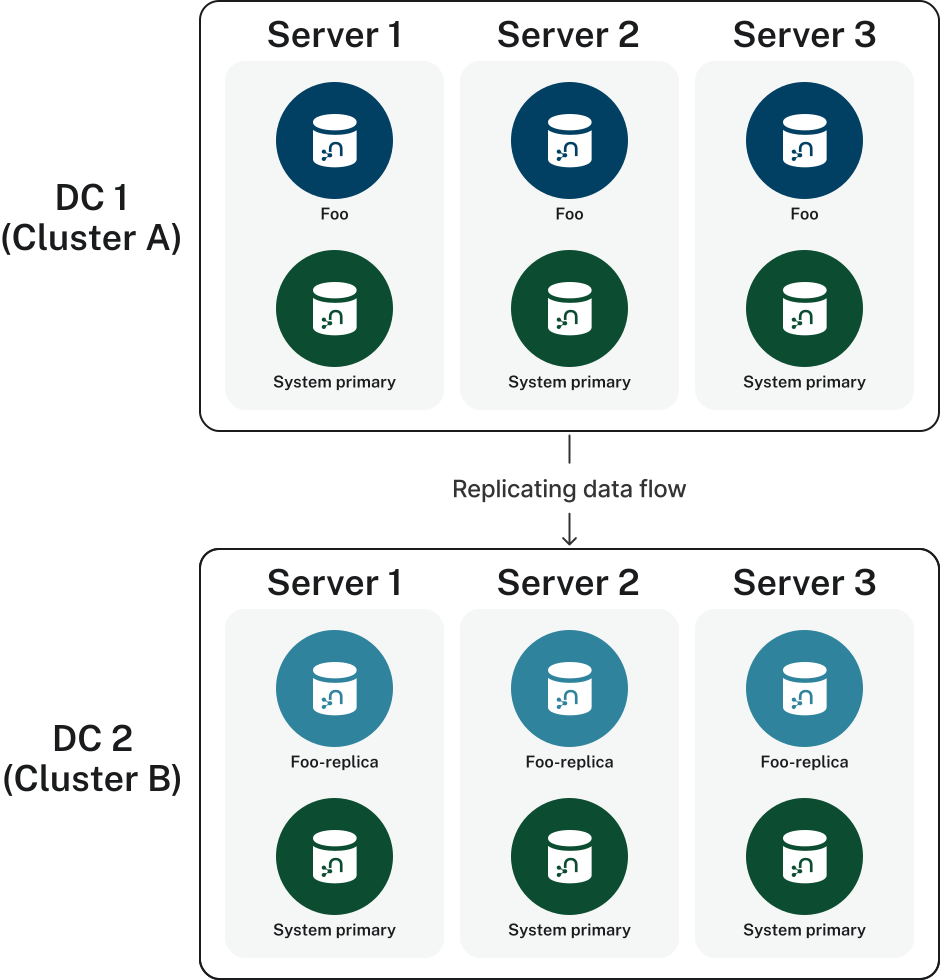
Each cluster has its own architecture.
Replication happens on a database level, not on a cluster member (server) level.
However, keep in mind, that user privileges and roles are not copied over when replicating a database, and the system database cannot be replicated.
This means permissions and role-based access control have to be configured separately on each cluster.
The replica database is always read-only. It can be promoted to become write-available if required.
For detailed instructions, see Replicating databases across clusters.
Recovering from the loss of the upstream database
If the source (upstream) database becomes unavailable, you can promote a replica database to accept writes.
Promotion is a one-way operation.
- Example recovery steps
-
-
Use the
dbms.promoteReplicaDatabase()procedure to promote a replica database. You can retain the current topology, or specify a new topology as part of the promotion. -
By running
SHOW DATABASES, verify that the former replica database is online on the desired number of servers and has typestandard.
-
For detailed information, see Replicating databases across clusters → Disaster recovery scenario.
Stretching a single cluster across multiple data centers
A single Neo4j cluster can be distributed across multiple locations, such as data centers or cloud regions.
Choosing this method of cluster deployment, you can achieve high availability, disaster recovery, and tolerance against the loss of a data center.
Taking into account cluster architecture and topology, you decide where database primaries and secondaries are located, balancing performance and fault tolerance. See Introduction: Neo4j clustering architecture for recommendations on database topologies.
Also, pay attention to networking and traffic routing:
-
If database primaries are distant from each other, that will increase your write latency.
-
To commit a change, the writer primary must get confirmation from a quorum of members, including itself. If primaries are far apart, network latency adds to commit time.
Read resilience with user database secondaries

For better read performance, you can locate all database primaries in one data center (DC) and the secondaries in another DC. This setup also provides fast writes, because they will be performed within the single DC.
However, if the DC with primaries goes down, your cluster loses write availability. Though read availability may remain via the secondaries.
Recovering from the loss of a data center
You can restore the cluster write availability without the failed DC:
-
If you have enough secondary members of the database in another DC, you can switch their mode to primary and not have to store a copy or wait a long time for primary copies to restore.
-
You can use secondaries to re-seed databases if needed. See the
dbms.recreateDatabase()procedure for more details.- Example recovery steps
-
-
Promote secondary copies of the
systemdatabase to primaries to make thesystemdatabase write-available. This requires restarting processes. For other scenarios, see the steps in the Disaster recovery guide on how to make thesystemdatabase write-available again. -
Mark missing servers as not available by cordoning them. For each
Unavailableserver, runCALL dbms.cluster.cordonServer("unavailable-server-id")on the remaining cluster. -
Recreate each user database, letting it choose the existing servers as seeders. You need to accept a smaller topology that will fit in the remaining DC.
-
For detailed scenarios, see the Disaster recovery guide.
Geo-distribution of primary databases

You can place each primary copy in a different data center (DC), using at least three data centers.
Therefore, if one DC fails, only a single primary member is lost, and the cluster can continue operating without data loss.
However, you always pay cross-data center latency times for every write operation.
Recovering from the loss of a data center
This setup has no loss of quorum, so the cluster keeps running — only with reduced fault tolerance (with no room for extra failures).
To restore fault tolerance, you can either wait until the affected DC is back online or start a new primary member somewhere else that will provide resilience and re-establish three-DC fault tolerance.
- Example recovery steps
-
-
Start and enable a new server. See How to add a server to the cluster for details.
-
Remove the unavailable server from the cluster:
-
First, deallocate databases from it.
-
Then drop the server.
For more information, visit the Managing servers in a cluster.
-
-
For detailed scenarios, see the Disaster recovery guide.
Exclusive geo-distribution for the system database

system database distributed across three data centersYou can place all primaries for user databases in one data center (DC) and all secondaries in another.
In a third DC, deploy a server that only hosts a primary of the system database (in addition to those in the first two data centers).
-
This server can be a small machine, since the
systemdatabase has minimal resource requirements. -
To prevent user databases from being allocated to it, set the
allowedDatabasesconstraint to some name that will never be used.
Your writes will be fast, because they occur within the single DC.
If a DC goes down, you retain write availability for the system database, which makes restoring write availability to the user databases easier.
However, if the DC with primaries goes down, the user databases will become write-unavailable. Though read availability may still be maintained via the secondaries.
Recovering from the loss of a data center
If you lose the DC with primaries in, the user databases will go write-unavailable, though the secondaries should continue to provide read availability.
Because of the third DC, the system database remains write-available, so you will be able to get the user databases back to write-available without process downtime.
However, if you need to use the dbms.recreateDatabase() procedure, it will involve downtime for the user database.
- Example recovery steps
-
-
Mark missing servers as not present by cordoning them. For each
Unavailableserver, runCALL dbms.cluster.cordonServer("unavailable-server-id")on one of the available servers. -
Recreate each user database, letting it select the existing servers as seeders. You need to accept a smaller topology that will fit in the remaining data center.
-
For detailed scenarios, see the Disaster recovery guide.
Fault tolerance to the failure of any two primaries

To tolerate the failure of any two arbitrary servers (or two primaries), the database must be configured with five primary allocations.
The configuration allows temporary removal of one primary while retaining fault tolerance, for example, when restarting one server for maintenance.
For multi-data center deployments, it is recommended to distribute five primaries across three data centers using the 2P+2P+1P layout.
You can also add secondaries, for example, to run backup jobs.
With this configuration, the cluster can tolerate the loss of any single data center.
Deployments using only two data centers (for example, 3P+2P or 4P+1P) or three data centers with an uneven distribution (such as 3P+1P+1P) are not recommended.
These configurations can only tolerate the loss of specific data centers rather than any data center.
If you possess a sufficient infrastructure, you can distribute five primaries across five data centers.
Recovering from the loss of a data center
This setup allows you to lose up to two primary database allocations or any single data center. Quorum is not lost, so the cluster keeps running.
If you lose three primaries, your database needs to be recreated since it has lost a majority of primary allocations and is therefore write-unavailable. However, the recreation can be based on the primary and secondary allocations still present on healthy servers, so a backup is not required.
- Example recovery steps
-
-
Start and enable new servers. See How to add a server to the cluster for details.
-
Mark missing servers as not present by cordoning them. For each
Unavailableserver, runCALL dbms.cluster.cordonServer("unavailable-server-id")on one of the available servers. -
For each
Cordonedserver, runDEALLOCATE DATABASES FROM SERVER cordoned-server-idon one of the available servers. This will move all database allocations from this server to an available server in the cluster. -
Remove unavailable servers from the cluster:
-
First, deallocate databases from it.
-
Then drop the server.
For more information, visit the Managing servers in a cluster.
-
-
For detailed scenarios, see the Disaster recovery guide.
Cluster design patterns to avoid
Two data centers with unbalanced membership

Suppose, you decide to set up just two data centers, placing two primaries in data center 1 (DC1) and one primary in the data center 2 (DC2).
If the writer primary is located in DC1, then writes can be fast because a local quorum can be reached.
This setup can tolerate the loss of one data center — but only if the failure is in DC2. If DC1 fails, you lose two primary members, which means the quorum is lost and the cluster becomes unavailable for writes.
Keep in mind that any issue could push the system back to cross–data center write latencies. Worse, because of the latency, the member in DC2 may fall behind. In that case a failure of a member in DC1 means the database is write-unavailable until the DC2 member has caught up.
If leadership shifts to DC2, this makes all writes slow.
Finally, there is no guarantee against data loss if DC1 goes down. Because the primary member in DC2 may not be up to date with writes, even in append.
Two data centers with balanced membership

The worst scenario is to operate with just two data centers and place two or three primaries in each of them.
This means the failure of either data center leads to loss of quorum and, therefore, to loss of the cluster write-availability.
Besides, all writes have to pay the cross-data center latency cost.
This design pattern is strongly recommended to avoid.
Summary
| Setup | Design | Pros | Cons | Best use case |
|---|---|---|---|---|
Multiple independent clusters |
||||
Independent clusters running in different locations |
Each cluster has its own architecture with a database replicating between them |
The clusters are fully independent of one another. In a disaster, a replica database can be promoted to take writes very quickly. |
|
This architecture is strongly recommended if you need regional failure isolation, allowing each region to operate autonomously and limiting the blast radius of infrastructure failures. |
A single cluster with database copies distributed across multiple data centers |
||||
Secondaries for read resilience |
Primaries in one data center, secondaries in other data centers |
|
|
Applications needing fast writes. The cluster can tolerate downtime during recovery. |
Geo-distributed data centers (3DC) |
Each primary in a different data center (≥3) |
|
|
Critical systems needing continuous availability even if a full data center fails. |
Full geo-distribution for the |
User database primaries in one DC, secondaries in another, |
|
|
Balanced approach: fast normal operations, easier recovery, some downtime acceptable. |
Tolerance to the failure of any two primaries (3DC) |
Five primaries distributed across three data centers |
|
|
Allows removal of one primary while retaining fault tolerance, e.g. restarting one server for maintenance. |
Non-recommended patterns |
||||
Two DCs – Unbalanced membership |
Two primaries are in DC1, one primary is in DC2. |
Fast writes if a leader is in DC1. |
|
Should be avoided. |
Two DCs – Balanced membership |
Equal primaries in two DCs. |
(none significant) |
|
Should be avoided. |
Glossary
- allocator
-
A component in the cluster that allocates databases to servers according to the topology constraints specified and an allocation strategy.
- asynchronous replication
-
Asynchronous replication is used by secondary copies to poll for new transactions, which means they cannot be guaranteed to have received the most recent transactions. This enables efficient scale-out of read-performance.
- Aura instance
-
A fully-managed DBMS represented by a single instance ID, that is running in the Neo4j Aura cloud.
- auto-commit transaction
-
An automatically committed transaction that contains a single query.
- Bolt protocol
-
Bolt is a protocol used for interaction between Neo4j instances and drivers.
- bookmark
-
A marker the client can request from the cluster to ensure that it is able to read its own writes so that the application’s state is consistent and only databases that have a copy of the bookmark are permitted to respond.
- category (Bloom)
-
A category is based on a node label and is defined in a Perspective as a way of visually distinguishing nodes with the same label(s).
- causal consistency
-
All servers in a cluster agree on the order in which transactions take place. The position of a server on the causal chain can be guaranteed using a bookmark.
- cluster
-
A Neo4j DBMS that spans multiple servers working together to increase fault tolerance and/or read scalability. Databases on a cluster may be configured to replicate across servers in the cluster thus achieving read scalability or high availability.
- client application
-
Software that interacts with a Neo4j server.
- commit
-
A commit is the successful completion of a transaction, which ensures durability of any changes made. For more details, visit Operations Manual → Transaction management.
- composite database
-
Composite databases are the means to access partitioned graph data with a single Cypher query.
- constraint
-
Constraints are sets of data modeling rules that ensure the data is consistent and reliable.
- Cypher®
-
Neo4j’s graph query language.
- data model
-
A data model defines how information is organized in a database. A good data model will make querying and understanding your data easier. In Neo4j, the data models have a graph structure.
- database
-
A database is a container used by the DBMS to manage and store graph data. The physical structure of data is controlled by the database.
- database vs graph
-
Databases are the physical containers of graph data. Graphs are the logical structure of data in Neo4j.
- Database Management System
-
Database Management System, or DBMS, capable of managing multiple databases. A DBMS may run on a single server, or span several servers configured as a cluster.
- database schema
-
The prescribed property existence and datatypes for nodes and relationships.
- deallocate
-
An act of removing a database from a server or a server from a cluster without loss of data or reduced fault tolerance.
- degree (of a node)
-
The number of relationships of a specific node; loops are counted twice.
- disaster recovery
-
A manual intervention to restore availability of a cluster, or databases within a cluster.
- driver
-
A software library that provides access to Neo4j from a particular programming language.
- election
-
In the event that the Raft leader becomes unresponsive, followers automatically trigger an election and vote for a new leader.
- entity
-
A node or a relationship.
- expression (Cypher)
-
A component of a Cypher query which produces values. It may be used in projections, as a predicate, or when setting properties on graph elements.
- fabric
-
Fabric is the architectural design of a unified system that provides a single access point to local or distributed graph data.
- fault tolerance
-
A guarantee that a cluster can maintain a database’s persistence and availability in the event of one or more servers failing.
- follower
-
A primary copy of a database acting as a follower, receives and acknowledges synchronous writes from the leader.
- Generative AI (GenAI)
-
A type of artificial intelligence (AI) system that generates text, images, or other media in response to prompts.
- graph
-
A logical representation of a set of nodes where some pairs are connected by relationships.
- index
-
Data structure that improves read performance of a database.
- knowledge graph
-
A specific type of graph that has an organizing principle so that a user (or a computer system) can reason about the underlying data. The organizing principle provides an additional layer of structure that adds context to support knowledge discovery.
- label
-
Marks a node as a member of a named and indexed subset. A node may be assigned zero or more labels.
- leader
-
A single primary copy of a database is designated as the leader. It receives all write transactions from clients and replicates writes synchronously to followers and asynchronously to secondary copies of the database.
- main database
-
In terms of Neo4j Enterprise Studio, the database(s) containing the user’s data. Can exist in the same Neo4j deployment as the tool asset database.
- motif
-
A description of a specific pattern within a graph.
- node
-
A node represents an entity or discrete object in your graph data model. Nodes can be connected by relationships, hold data in properties, and are classified by labels.
- operator
-
A symbol representing a mathematical or logical operation.
- parameter
-
Named value provided when running a Cypher statement.
- path
-
A sequence of nodes and the relationships connecting them, that does not contain duplicate relationships. Several paths can match a pattern.
- pattern
-
A specific arrangement of nodes and relationships that can be matched in a graph. A pattern follows a motif.
- perspective (Bloom)
-
A Perspective defines a certain business view or domain that can be found in the target Neo4j graph. A single Neo4j graph can be viewed through different Perspectives, each tailored for a different business purpose.
- primary
-
A copy of the database that is able to process write transactions and is eligible to be elected as a leader. It participates in fault tolerant writes as it is part of the majority required to acknowledge and commit write transactions.
- primary vs secondary
-
In a cluster, databases can operate in either primary or secondary mode. Primary databases are able to process write and read transactions, ensuring fault tolerance. Secondary databases are replicated asynchronously from primaries, and their main purpose is to provide read scaling within the cluster.
- project (Aura)
-
An isolated environment in the unified Aura console that contains its own database instances, configurations, and resources. Preceded by tenant in the classic Aura console.
- property
-
Properties are key-value pairs that are used for storing data on nodes and relationships.
- query (Cypher)
-
A statement that retrieves or writes information to a database.
- Raft group
-
A group of servers that are participating in hosting a particular database in primary mode.
- Raft group member
-
A server that is participating in a Raft group. A server can be a member of one or more groups.
- Raft log
-
A shared log between all Raft group members that is guaranteed to be consistently updated and viewed by those members. The log contains both database data and operational state of the Raft group.
- Raft protocol
-
The networking mechanism that enables a database to replicate its data across multiple servers to give high availability for accessing the data and high durability to the data stored.
- read scaling
-
Distributing query load by creating additional database copies hosted in secondary mode (read-only).
- relationship
-
A relationship represents a connection between nodes in your graph data model. Relationships connect a source node to a target node, hold data in properties, and are classified by type.
- secondary
-
An asynchronously replicated copy of the database that provides read scaling within the cluster.
- seed
-
A seed is a database dump or a full backup used to create a database on a cluster. This is sometimes called seeding.
- server
-
A physical machine, a virtual machine, or a container running an instance of Neo4j. Servers can be standalone or part of a cluster.
- session
-
A causally linked sequence of transactions.
- session consistency
-
An alternative name for Neo4j’s causal consistency.
- standalone
-
A single server running Neo4j and not part of a cluster.
- synchronous replication
-
Synchronous replication requires the leader primary to replicate a transaction and block the commit until a quorum of the follower primaries acknowledges that the transaction is successfully replicated. Once the transaction is replicated, the commit is allowed to proceed. This ensures data durability and consistency within the cluster.
- system database
-
A database used by Neo4j to store system information.
- tenant (Aura)
-
An isolated environment in the classic Aura console that contains its own database instances, configurations, and resources. Replaced by project in the unified Aura console.
- tool asset database
-
In terms of Neo4j Enterprise Studio, the database where tools' assets are stored. This can be in the same Neo4j deployment as the main database(s) or in a separate deployment.
- topology
-
A configuration that describes how the copies of a database should be spread across the servers in a cluster, see primary mode and secondary mode.
- transaction
-
A transaction comprises a unit of work performed against a database. It is treated in a coherent and reliable way, independent of other transactions. Transactions comply with the ACID consistency model (atomic, consistent, isolated, and durable).