Replicating databases across clustersCypher 25Enterprise EditionNot available on AuraIntroduced in 2026.08
Overview
In 2026.08, cross-cluster database replication (CCDR) is officially released. This provides the functionality for one database in a cluster to be replicated over to another cluster. The original database is called upstream or source, while the database that replicates data is called the replica.
There are two mechanisms for replicating databases across clusters:
-
Replication via the network (see Figure 1).
-
Replication via backups (see Figure 2).
Both mechanisms poll for new transactions/backups and apply them as soon as new transactions/backups become available.

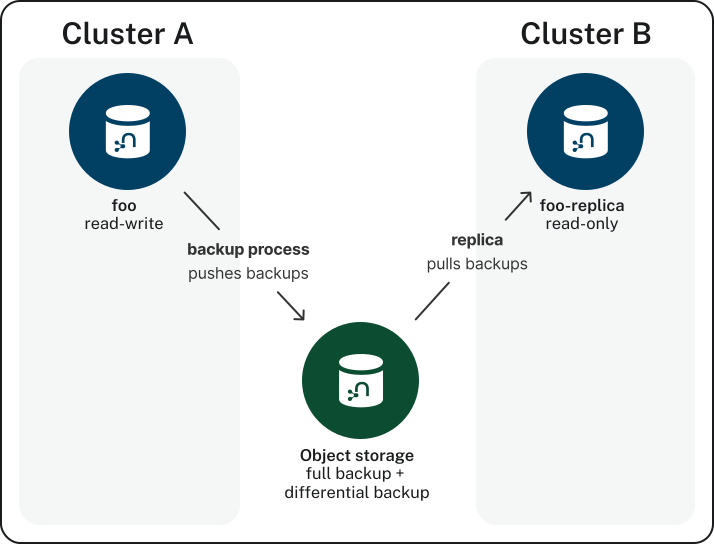
The commands and procedures for creating and promoting replica databases are supported by Cypher 25.
All replica databases are read-only. A replica database can have topology with primary and secondary copies that follow the servers' mode constraints. However, both primaries and secondaries remain read-only. Neither replica primaries nor replica secondaries accept write operations.
|
Only standard databases can be used as upstream sources for cross-cluster database replication. Composite databases and sharded property databases (SPD) are not supported as replication sources. |
Creating a replica database via the network
This creation method is recommended when the two clusters are directly connected over the network. Inter-cluster encryption and mutual trust between the clusters are also strongly recommended.
CREATE REPLICA DATABASE name
[[SET] TOPOLOGY n PRIMAR{Y|IES} [m SECONDAR{Y|IES}]]
OPTIONS {replicaConfig: {remote: upstreamDatabaseName, addresses: remoteAddresses}}
[WAIT [n [SEC[OND[S]]]]|NOWAIT]| Option | Description |
|---|---|
|
Replica config of upstream details to pull from. Type: Defines the upstream information for the replica to pull from. Possible keys of this map include:
|
Example
Let’s assume you have two separate clusters running independently from each other: Cluster A and Cluster B.
On Cluster A, the database foo is running and has three servers with cluster addresses: server01.example.com:6000, server02.example.com:6000, server03.example.com:6000.
On Cluster B, run the following command to create a replica database foo-replica (three primaries, two secondaries) that will replicate from the upstream database foo on Cluster A:
CREATE REPLICA DATABASE `foo-replica`
TOPOLOGY 3 PRIMARIES 2 SECONDARIES
OPTIONS {
  replicaConfig: {
    remote: "foo",
    addresses: [
      "server01.example.com:6000",
      "server02.example.com:6000",
      "server03.example.com:6000"
    ]
  }
};
The command can only be executed successfully if the replica database is able to contact the remote cluster endpoints listed in addresses.
If not, the command results in an error.
|
You can also create a replica database from a database backup using If a After initial seeding, the replica pulls transactions from the upstream database using the servers listed in |
By running the SHOW DATABASES command, you can verify that the foo-replica database is online on the desired number of servers, in the desired roles.
Note that the database type is replica, and the options column shows its configuration.
SHOW DATABASE `foo-replica` YIELD name, type, access, address, role, writer, options;+-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| name | type | access | address | role | writer | options |
+-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| "foo-replica" | "replica" | "read-only" | "localhost:7687" | "primary" | FALSE | {replicaConfig: {remote: "foo", addresses: ["server01.example.com:6000", "server02.example.com:6000", "server03.example.com:6000"]}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7688" | "primary" | FALSE | {replicaConfig: {remote: "foo", addresses: ["server01.example.com:6000", "server02.example.com:6000", "server03.example.com:6000"]}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7689" | "primary" | FALSE | {replicaConfig: {remote: "foo", addresses: ["server01.example.com:6000", "server02.example.com:6000", "server03.example.com:6000"]}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7690" | "secondary" | FALSE | {replicaConfig: {remote: "foo", addresses: ["server01.example.com:6000", "server02.example.com:6000", "server03.example.com:6000"]}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7691" | "secondary" | FALSE | {replicaConfig: {remote: "foo", addresses: ["server01.example.com:6000", "server02.example.com:6000", "server03.example.com:6000"]}} |
+-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
5 rows available after 3 ms, consumed after another 1 ms
Configuring inter-cluster encryption
Firstly, ensure that each cluster is encrypted using intra-cluster encryption. To ensure that both Cluster A and Cluster B can mutually authenticate, each cluster must trust the Certificate Authority (CA) that signs the other cluster’s certificates.
If clusters use different CAs, the CA certificate of Cluster A must be installed in the trusted/ directory of Cluster B, and vice versa.
For example, here is one possible certificate folder configuration:
ClusterA

cluster/
├── private.key                 ← clusterA node private key
├── public.crt                  ← clusterA node certificate
├── trusted/
│   └── clusterB-ca.crt         ← CA that signs ClusterB node certs
└── revoked/


ClusterB

cluster/
├── private.key                 ← ClusterB node private key
├── public.crt                  ← ClusterB node certificate
├── trusted/
│   └── clusterA-ca.crt         ← CA that signs ClusterA node certs
└── revoked/
Recovery point objective (RPO)
Network replication streams transactions from the upstream database to the replica. This provides a near-zero recovery point objective (RPO), subject to any asynchronous replication lag between the upstream and replica databases.
To configure a catchup interval, modify the db.cluster.catchup.pull_interval setting, which defaults to one second (1s).
For details about monitoring replication lag, see Monitoring replica databases.
Creating a replica database with remote backup pulling
Replication can also be done by retrieving backups through cloud object storage or a file system (see Figure 2). The advantage of this approach is that it eliminates the need for a direct network connection between the clusters.
CREATE REPLICA DATABASE name
[[SET] TOPOLOGY n PRIMAR{Y|IES} [m SECONDAR{Y|IES}]]
OPTIONS {replicaConfig: {remote: upstreamDatabaseName, pullURI: backupURI}}
[WAIT [n [SEC[OND[S]]]]|NOWAIT]| Option | Description |
|---|---|
|
Replica configuration of upstream details to pull from. Type: Defines the upstream information for the replica to pull from. Possible keys of this map include:
|
|
The backup-producing process and the replica database need access to the object storage location used by |
Initialization of a replica
Initialization starts from a complete backup chain. A complete backup chain contains a full backup and, optionally, some number of differential backups that follow it without gaps. You have to create and push the complete backup chain to the bucket or file-system location used for replica initialization.

When only pullURI is specified, the complete backup chain must be available at pullURI.
The replica initializes its store from that backup chain.
To create a replica, run the following command:
CREATE REPLICA DATABASE `foo-replica`
TOPOLOGY 3 PRIMARIES 1 SECONDARY
OPTIONS {
  replicaConfig: {
    remote: "foo",
    pullURI: "s3://myBucket//"
  }
};|
You can also create a replica database from a database backup using If a
|
Running a replica
After initialization, a replica database consumes only differential backups from pullURI.
The differential backup chain must remain unbroken from the replica database’s current point onward.
You are responsible for continuing to create and push differential backups from the upstream database to the pullURI location.

To view the replica configuration, yield the options column:
SHOW DATABASE `foo-replica` YIELD name, type, access, address, role, writer, options;+-------------------------------------------------------------------------------------------------------------------------------------------------+
| name | type | access | address | role | writer | options |
+-------------------------------------------------------------------------------------------------------------------------------------------------+
| "foo-replica" | "replica" | "read-only" | "localhost:7687" | "primary" | FALSE | {replicaConfig: {remote: "foo", pullURI: "s3://myBucket/"}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7688" | "primary" | FALSE | {replicaConfig: {remote: "foo", pullURI: "s3://myBucket/"}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7689" | "primary" | FALSE | {replicaConfig: {remote: "foo", pullURI: "s3://myBucket/"}} |
| "foo-replica" | "replica" | "read-only" | "localhost:7690" | "secondary" | FALSE | {replicaConfig: {remote: "foo", pullURI: "s3://myBucket/"}} |
+-------------------------------------------------------------------------------------------------------------------------------------------------+
Recovery point objective (RPO)
RPO is determined by the frequency of differential backup creation and transmission, combined with the replica pull interval.
A replica database checks for new differential backups at the interval configured by db.cluster.backup.pull_interval, which defaults to 1 minute (1m).
To achieve a low RPO:
-
Increase backup frequency: create and push differential backups more often.
-
Reduce the pull interval if needed.
-
Use network replication, which streams transactions continuously and provides a near-zero RPO.
For example, with hourly differential backups and the default 1-minute pull interval, failover can result in up to one hour of data loss. Increasing differential backup frequency to every 10 minutes while keeping the default 1-minute pull interval reduces potential data loss up to 10–15 minutes. Note that the true RPO is dependent on time taken for the backup created, uploaded, pulled, and applied - and this is heavily dependent on workload.
As such it is important to implement observability tools to track the replication lag between the upstream and replica databases (see Monitoring replica databases). Growing lag often indicates a broken differential backup chain, which stops the replica from pulling new updates. If this occurs, you must recreate the replica database from a complete backup chain before it can continue applying differential backups.
Accessing replica databases via drivers or Cypher Shell
Given that replica databases are read-only, you must ensure that the drivers either have "AccessMode" set to "READ", or are only doing executeRead.
Attempts to write to the replica database will fail.
Furthermore, when accessing the database via Cypher Shell, ensure that --access-mode is also set to read when connecting.
bin/cypher-shell --access-mode=read -a neo4j://localhost:7684 -d foo-replicaThis is necessary because all our replicas are read-only.
Failure to do so would result in failure to find a WRITE server.
When accessing the database via the Neo4j Browser, ensure that the Access mode is set to Read. This can be found in the Browser Settings drawer.
Setting up routing policies
Replica databases respect the built-in routing policies.
- Example 1
-
For example, if you have no routing policies, querying the
CALL dbms.routing.getRoutingTable({}, "foo-replica");returns all five servers you have as readers and no writers:+-------------------------------------------------------------------------------------------------------------------------------+ | ttl | servers | +-------------------------------------------------------------------------------------------------------------------------------+ | 300 | [{addresses: ["localhost:7687", "localhost:7688", "localhost:7689", "localhost:7690", "localhost:7691"], role: "READ"} | +-------------------------------------------------------------------------------------------------------------------------------+ - Example 2
-
If you set
dbms.routing.reads_on_primaries_enabled=falsein the neo4j.conf file to disable reads on primaries, the routing policy results in the following routing table where only the two replicas with secondary role are readers:+-------------------------------------------------------------------------+ | ttl | servers | +-------------------------------------------------------------------------+ | 300 | [{addresses: ["localhost:7690", "localhost:7691"], role: "READ"} | +-------------------------------------------------------------------------+
Managing user roles and privileges
|
User privileges and roles are not copied over when replicating a database. |
Permissions and role-based access control have to be set up separately on Cluster A and Cluster B as they cannot be copied over.
You should treat the two clusters as independent entities, with a standard database replicating between them.
Furthermore, the system database cannot be replicated.
Monitoring replica databases
Replicas asynchronously replicate data from the upstream database.
Therefore, it is important to track the replication lag between the upstream and the replica databases.
In order to do this, plot the <prefix>.database.<db>.transaction.last_committed_tx_id metric for both the upstream and replica databases.
This difference effectively captures the lag between the upstream and the replica.
Versions and upgrades
Differing versions upstream and downstream
The downstream cluster where the replica database is created must run Neo4j 2026.08 or later. The upstream cluster can run Neo4j 2025.01 or later, but must not run a version later than the downstream cluster.
Upgrade order
When upgrading clusters that participate in cross-cluster database replication, upgrade the downstream cluster before the upstream cluster.
Upgrade types
When using network-based replication, the server addresses specified in replicaConfig.addresses at replica creation time are fixed and cannot be changed afterwards.
The replica uses these exact addresses to connect to the upstream cluster.
This means that:
-
DNS-based upgrades and in-place rolling upgrades are safe, because the server addresses remain the same.
-
New server rolling upgrades, where new servers with different addresses replace the original ones, will cause replication to fail because the replica cannot discover the new addresses.
If you need to change the upstream addresses used by a replica, you must drop and recreate the replica database with the new addresses.
Disaster recovery scenario
It is recommended to set up two independent clusters in two different cloud regions. If the main region has gone down, you can promote the replicating database in the disaster recovery cluster (DR-cluster) and redirect data traffic to the promoted database.

Figure 5. Disaster
|

Figure 6. Promoting the replica database
|

Figure 7. Redirecting data traffic
|
Promoting a replica database
If the source cluster becomes unavailable, you can promote a replica database to accept writes.
|
Promotion is a one-way operation. Once a replica is promoted, it cannot be re-attached to the original source. To resume replication, you need to create a new replica. |
Use the dbms.promoteReplicaDatabase() procedure to promote a replica database.
You can retain the current topology, or specify a new topology as part of the promotion.
Syntax |
|
||
Description |
Convert a replica database to a standard database while keeping the data it currently has. |
||
Input arguments |
Name |
Type |
Description |
|
|
The name of the replica in the current cluster which is going to be promoted. |
|
|
|
A map with optional topology settings for the promoted database. Use an empty map to retain the current topology. |
|
|
|
Optional key in |
|
|
|
Optional key in |
|
Mode |
WRITE |
||
On Cluster B, to promote the replica database foo-replica with the existing topology which is three primaries and two secondaries, call the procedure with an empty options map:
CALL dbms.promoteReplicaDatabase('foo-replica', {});You can also alter the replica’s topology during promotion:
CALL dbms.promoteReplicaDatabase('foo-replica', {primaries: 3, secondaries: 4});This will promote the replica database with three primaries and four secondaries.
The database becomes write-available.
Verify that the foo-replica database is online on the desired number of servers and has type standard.
SHOW DATABASE `foo-replica`;+----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+ | name | type | aliases | access | address | role | writer | requestedStatus | currentStatus | statusMessage | default | home | constituents| +----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+ | "foo-replica" | "standard" | [] | "read-write" | "localhost:7687" | "primary" | TRUE | "online" | "online" | "" | FALSE | FALSE | [] | | "foo-replica" | "standard" | [] | "read-write" | "localhost:7688" | "primary" | FALSE | "online" | "online" | "" | FALSE | FALSE | [] | | "foo-replica" | "standard" | [] | "read-write" | "localhost:7689" | "primary" | FALSE | "online" | "online" | "" | FALSE | FALSE | [] | | "foo-replica" | "standard" | [] | "read-write" | "localhost:7690" | "secondary" | FALSE | "online" | "online" | "" | FALSE | FALSE | [] | | "foo-replica" | "standard" | [] | "read-write" | "localhost:7691" | "secondary" | FALSE | "online" | "online" | "" | FALSE | FALSE | [] | +----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+ 5 rows available after 3 ms, consumed after another 1 ms
One of the primary databases is now write-available because the writer value is TRUE.
At this point, our routing tables will return both writers and readers as per a standard database.
Failback
Failback is the process of restoring the main cluster back into operation after a DR scenario. This is under the assumption that the promoted database is currently running in the DR-cluster.
To restore the previous source database, follow the steps:
-
In the current example, the replica database’s upstream is the promoted database
foo-replicain the DR-cluster, Cluster B (see Figure 8).
Create a replica databasefooin the main cluster which is Cluster A. Figure 8. Recovery after a disaster
-
Stop write operations on the promoted database
foo-replicain Cluster B. -
Check the metrics to ensure that
tx_idis exactly the same for both the promoted and replicating databases. -
Promote the replica database
fooin Cluster A, meaning that this database starts serving write operations and becomes again the main database serving traffic. -
Stop and drop the database
foo-replicain the DR-cluster. Create a new replicafoo-new-replicawith the upstream pointing to the main databasefooin the main cluster. Figure 9. Restoring the upstream database in the main cluster
Glossary
- allocator
-
A component in the cluster that allocates databases to servers according to the topology constraints specified and an allocation strategy.
- asynchronous replication
-
Asynchronous replication is used by secondary copies to poll for new transactions, which means they cannot be guaranteed to have received the most recent transactions. This enables efficient scale-out of read-performance.
- Aura instance
-
A fully-managed DBMS represented by a single instance ID, that is running in the Neo4j Aura cloud.
- auto-commit transaction
-
An automatically committed transaction that contains a single query.
- Bolt protocol
-
Bolt is a protocol used for interaction between Neo4j instances and drivers.
- bookmark
-
A marker the client can request from the cluster to ensure that it is able to read its own writes so that the application’s state is consistent and only databases that have a copy of the bookmark are permitted to respond.
- category (Bloom)
-
A category is based on a node label and is defined in a Perspective as a way of visually distinguishing nodes with the same label(s).
- causal consistency
-
All servers in a cluster agree on the order in which transactions take place. The position of a server on the causal chain can be guaranteed using a bookmark.
- cluster
-
A Neo4j DBMS that spans multiple servers working together to increase fault tolerance and/or read scalability. Databases on a cluster may be configured to replicate across servers in the cluster thus achieving read scalability or high availability.
- client application
-
Software that interacts with a Neo4j server.
- commit
-
A commit is the successful completion of a transaction, which ensures durability of any changes made. For more details, visit Operations Manual → Transaction management.
- composite database
-
Composite databases are the means to access partitioned graph data with a single Cypher query.
- constraint
-
Constraints are sets of data modeling rules that ensure the data is consistent and reliable.
- Cypher®
-
Neo4j’s graph query language.
- data model
-
A data model defines how information is organized in a database. A good data model will make querying and understanding your data easier. In Neo4j, the data models have a graph structure.
- database
-
A database is a container used by the DBMS to manage and store graph data. The physical structure of data is controlled by the database.
- database vs graph
-
Databases are the physical containers of graph data. Graphs are the logical structure of data in Neo4j.
- Database Management System
-
Database Management System, or DBMS, capable of managing multiple databases. A DBMS may run on a single server, or span several servers configured as a cluster.
- database schema
-
The prescribed property existence and datatypes for nodes and relationships.
- deallocate
-
An act of removing a database from a server or a server from a cluster without loss of data or reduced fault tolerance.
- degree (of a node)
-
The number of relationships of a specific node; loops are counted twice.
- disaster recovery
-
A manual intervention to restore availability of a cluster, or databases within a cluster.
- driver
-
A software library that provides access to Neo4j from a particular programming language.
- election
-
In the event that the Raft leader becomes unresponsive, followers automatically trigger an election and vote for a new leader.
- entity
-
A node or a relationship.
- expression (Cypher)
-
A component of a Cypher query which produces values. It may be used in projections, as a predicate, or when setting properties on graph elements.
- fabric
-
Fabric is the architectural design of a unified system that provides a single access point to local or distributed graph data.
- fault tolerance
-
A guarantee that a cluster can maintain a database’s persistence and availability in the event of one or more servers failing.
- follower
-
A primary copy of a database acting as a follower, receives and acknowledges synchronous writes from the leader.
- Generative AI (GenAI)
-
A type of artificial intelligence (AI) system that generates text, images, or other media in response to prompts.
- graph
-
A logical representation of a set of nodes where some pairs are connected by relationships.
- index
-
Data structure that improves read performance of a database.
- knowledge graph
-
A specific type of graph that has an organizing principle so that a user (or a computer system) can reason about the underlying data. The organizing principle provides an additional layer of structure that adds context to support knowledge discovery.
- label
-
Marks a node as a member of a named and indexed subset. A node may be assigned zero or more labels.
- leader
-
A single primary copy of a database is designated as the leader. It receives all write transactions from clients and replicates writes synchronously to followers and asynchronously to secondary copies of the database.
- main database
-
In terms of Neo4j Enterprise Studio, the database(s) containing the user’s data. Can exist in the same Neo4j deployment as the tool asset database.
- motif
-
A description of a specific pattern within a graph.
- node
-
A node represents an entity or discrete object in your graph data model. Nodes can be connected by relationships, hold data in properties, and are classified by labels.
- operator
-
A symbol representing a mathematical or logical operation.
- parameter
-
Named value provided when running a Cypher statement.
- path
-
A sequence of nodes and the relationships connecting them, that does not contain duplicate relationships. Several paths can match a pattern.
- pattern
-
A specific arrangement of nodes and relationships that can be matched in a graph. A pattern follows a motif.
- perspective (Bloom)
-
A Perspective defines a certain business view or domain that can be found in the target Neo4j graph. A single Neo4j graph can be viewed through different Perspectives, each tailored for a different business purpose.
- primary
-
A copy of the database that is able to process write transactions and is eligible to be elected as a leader. It participates in fault tolerant writes as it is part of the majority required to acknowledge and commit write transactions.
- primary vs secondary
-
In a cluster, databases can operate in either primary or secondary mode. Primary databases are able to process write and read transactions, ensuring fault tolerance. Secondary databases are replicated asynchronously from primaries, and their main purpose is to provide read scaling within the cluster.
- project (Aura)
-
An isolated environment in the unified Aura console that contains its own database instances, configurations, and resources. Preceded by tenant in the classic Aura console.
- property
-
Properties are key-value pairs that are used for storing data on nodes and relationships.
- query (Cypher)
-
A statement that retrieves or writes information to a database.
- Raft group
-
A group of servers that are participating in hosting a particular database in primary mode.
- Raft group member
-
A server that is participating in a Raft group. A server can be a member of one or more groups.
- Raft log
-
A shared log between all Raft group members that is guaranteed to be consistently updated and viewed by those members. The log contains both database data and operational state of the Raft group.
- Raft protocol
-
The networking mechanism that enables a database to replicate its data across multiple servers to give high availability for accessing the data and high durability to the data stored.
- read scaling
-
Distributing query load by creating additional database copies hosted in secondary mode (read-only).
- relationship
-
A relationship represents a connection between nodes in your graph data model. Relationships connect a source node to a target node, hold data in properties, and are classified by type.
- secondary
-
An asynchronously replicated copy of the database that provides read scaling within the cluster.
- seed
-
A seed is a database dump or a full backup used to create a database on a cluster. This is sometimes called seeding.
- server
-
A physical machine, a virtual machine, or a container running an instance of Neo4j. Servers can be standalone or part of a cluster.
- session
-
A causally linked sequence of transactions.
- session consistency
-
An alternative name for Neo4j’s causal consistency.
- standalone
-
A single server running Neo4j and not part of a cluster.
- synchronous replication
-
Synchronous replication requires the leader primary to replicate a transaction and block the commit until a quorum of the follower primaries acknowledges that the transaction is successfully replicated. Once the transaction is replicated, the commit is allowed to proceed. This ensures data durability and consistency within the cluster.
- system database
-
A database used by Neo4j to store system information.
- tenant (Aura)
-
An isolated environment in the classic Aura console that contains its own database instances, configurations, and resources. Replaced by project in the unified Aura console.
- tool asset database
-
In terms of Neo4j Enterprise Studio, the database where tools' assets are stored. This can be in the same Neo4j deployment as the main database(s) or in a separate deployment.
- topology
-
A configuration that describes how the copies of a database should be spread across the servers in a cluster, see primary mode and secondary mode.
- transaction
-
A transaction comprises a unit of work performed against a database. It is treated in a coherent and reliable way, independent of other transactions. Transactions comply with the ACID consistency model (atomic, consistent, isolated, and durable).